



The First 5 Minutes of a Critical Incident: What Goes Wrong & How to Get It Right
Somewhere on site, something has just gone wrong. The details are still coming in, and nobody has the full picture yet. The first five minutes decide everything that follows. Get them right and the response stays controlled. Get them wrong and a manageable situation turns into a much bigger problem.
It’s easy to assume the hard part of incident management is the big, dramatic response: the evacuation, the lockdown, the call to emergency services. In practice, most of that response is shaped long before any of it happens, in a window most teams barely think about. This article looks at why those first five minutes carry so much weight, where things typically go wrong, and what a well-run response actually looks like in practice.
For more information on Incident Management, read our Complete Guide to Incident Management
Why the First Five Minutes Matter So Much
A critical incident rarely announces itself clearly. The first report is usually partial, sometimes wrong, and often coming from more than one person at once. Whoever is on shift has to make sense of it fast, with limited information and no time to double-check. Decisions made in this window set the tone for the whole response.
There’s a reason emergency services and clinical teams train specifically for the first moments of a crisis rather than just the middle and end of it. The early stage of any incident is where uncertainty is highest, and uncertainty is exactly when people default to habit. If the habit is good, that’s a strength. If the habit is disorganised, guesswork fills the gap, and guesswork rarely holds up under scrutiny afterwards.
The first five minutes also set the factual record. Whatever gets written down, or doesn’t, in that window becomes the version of events everyone refers back to later, including insurers, clients, and regulators. Getting that record right from the outset saves a lot of reconstruction later.
What Typically Goes Wrong
No single source of truth: One guard sees something and radios it in. Another logs it differently in the occurrence book. A third mentions it to the control room verbally and nobody writes it down at all. Within minutes, three different versions of the same event exist, and nobody is fully sure what actually happened.
Delayed or unclear escalation: Teams often lose time working out who needs to know, and in what order. A guard waits for a supervisor to confirm before escalating further. The supervisor is on another call. Ten minutes disappear before the right people are even aware.
Handover gaps: Shift changes are a common failure point. An incident starts at the end of one shift and the details don’t fully transfer to the next. The incoming team is left reconstructing what happened from a partial note.
No clear record for what happens next: Even when the initial response goes well, the paper trail often doesn’t. Insurers, clients, and internal review boards all ask for evidence of what was known and when. If the first five minutes were logged loosely, that evidence is thin.
Conflicting instructions: When more than one person tries to direct the response at once, without a clear line of authority, guards on the ground can end up receiving contradictory instructions within the same minute. Confusion about who’s actually in charge slows everything down.
Reliance on personal memory: Teams that don’t log incidents as they happen end up relying on someone recalling the sequence of events afterwards, often hours later. Details get lost, timings get rounded, and the record ends up softer than it should be.
No mobile access to logging tools: If reporting an incident means finding a desk and a desktop terminal, most of the first five minutes are spent walking rather than logging. Guards on the floor need to be able to report from wherever they are.
What This Actually Costs When It Goes Wrong
The consequences of a poor first five minutes rarely show up immediately. They show up weeks later, when a client asks for a full account of what happened and the record is patchy. They show up when an insurer challenges a claim because the timeline doesn’t hold together. They show up when a legal team needs to establish exactly what the security team knew, and when, and the honest answer is that nobody wrote it down clearly enough to say.
There’s also a quieter, ongoing cost. Teams that operate without a clear process for the opening minutes of an incident tend to build up a kind of institutional fatigue, where every incident feels slightly chaotic even when the outcome is fine. That fatigue affects morale and, over time, affects how seriously staff take the reporting process itself. A team that trusts its own system logs things properly. A team that doesn’t, starts cutting corners.
What Good Looks Like
Picture a similar scenario handled well. A guard on patrol notices something out of place and logs it immediately from a mobile device, with a timestamp and a short description. The moment that report lands, the system flags it to the control room and, based on a predefined escalation path, notifies the shift supervisor automatically. No one has to remember who to call.
The supervisor sees the same report the guard filed, not a secondhand summary, and can add context immediately. If the incident escalates further, that same log carries every update, so anyone joining the response midway, including someone arriving on the next shift, can see exactly what’s happened and what’s already been done. Nothing needs to be explained twice.
By the time the incident is resolved, there’s a single, time-stamped record from the first report to the last update. If a client, insurer, or internal review asks what happened and when, the answer already exists. Nobody has to reconstruct it from memory or piece it together from three different notebooks.
How to Get It Right
Capture everything in one place, in real time: Every report, however small, should land in a single system the moment it happens rather than being pieced together afterwards. An incident management system that captures reports as they come in gives everyone the same version of events from the outset.
Build escalation into the process, not into memory: The decision about who gets notified, and when, shouldn’t rely on someone remembering the chain of command under pressure. Predefined escalation paths, triggered automatically as an incident is logged, close the gap between “something happened” and “the right people know.”
Treat handover as part of incident response, not separate from it: Live incidents need to transfer cleanly between shifts, with full context, not a verbal summary at the door. A shared, real-time incident log means the next shift picks up exactly where the last one left off.
Timestamp everything: A clear, time-stamped record from the first report onward is what turns a chaotic first few minutes into a defensible, reviewable process afterwards. This matters as much for compliance and client reporting as it does for the response itself.
Give frontline staff mobile-first tools: Reporting needs to happen from wherever the incident is, not from a fixed terminal. Mobile access to logging removes the delay between noticing something and recording it.
Assign clear ownership before anything happens: Every site should know, in advance, who has authority to direct a response and who they answer to. That decision shouldn’t be made in the moment.
Review the first five minutes after every incident, not just the outcome: Debriefs tend to focus on how an incident ended. Looking specifically at how the opening minutes were handled, what was logged, how fast escalation happened, surfaces the gaps that are easiest to fix.
Why Process Beats Instinct Here
None of this is a criticism of experienced teams. Experience is what allows someone to correctly judge that a situation is serious within seconds. What experience doesn’t do is guarantee that three colleagues will log the same event consistently, or that a message will reach the right supervisor without depending on someone happening to answer their radio. Process and instinct aren’t competing with each other. Good process is what lets instinct actually be useful, because it removes the administrative uncertainty around who does what and when, leaving the team free to focus on the judgement calls that genuinely need a human being.
This is also why bolting on more training rarely fixes a first-five-minutes problem on its own. Training improves judgement. It doesn’t fix a structural gap where an incident can be reported to three different places and end up properly recorded in none of them. That’s a systems problem, and it needs a systems answer.
The first five minutes of an incident test process as much as people. Even a well-trained team can be let down by information sitting in different places, or an escalation step that depends on someone being reachable at exactly the right moment. Tightening up how information is captured and shared from the first report onward is what closes that gap.
None of this replaces training, judgement, or a calm head under pressure. What it does is make sure that calm head has the right information, the right escalation path, and a clear record, from the first second an incident starts. That’s the difference between a response that holds together and one that has to be pieced back together afterwards.
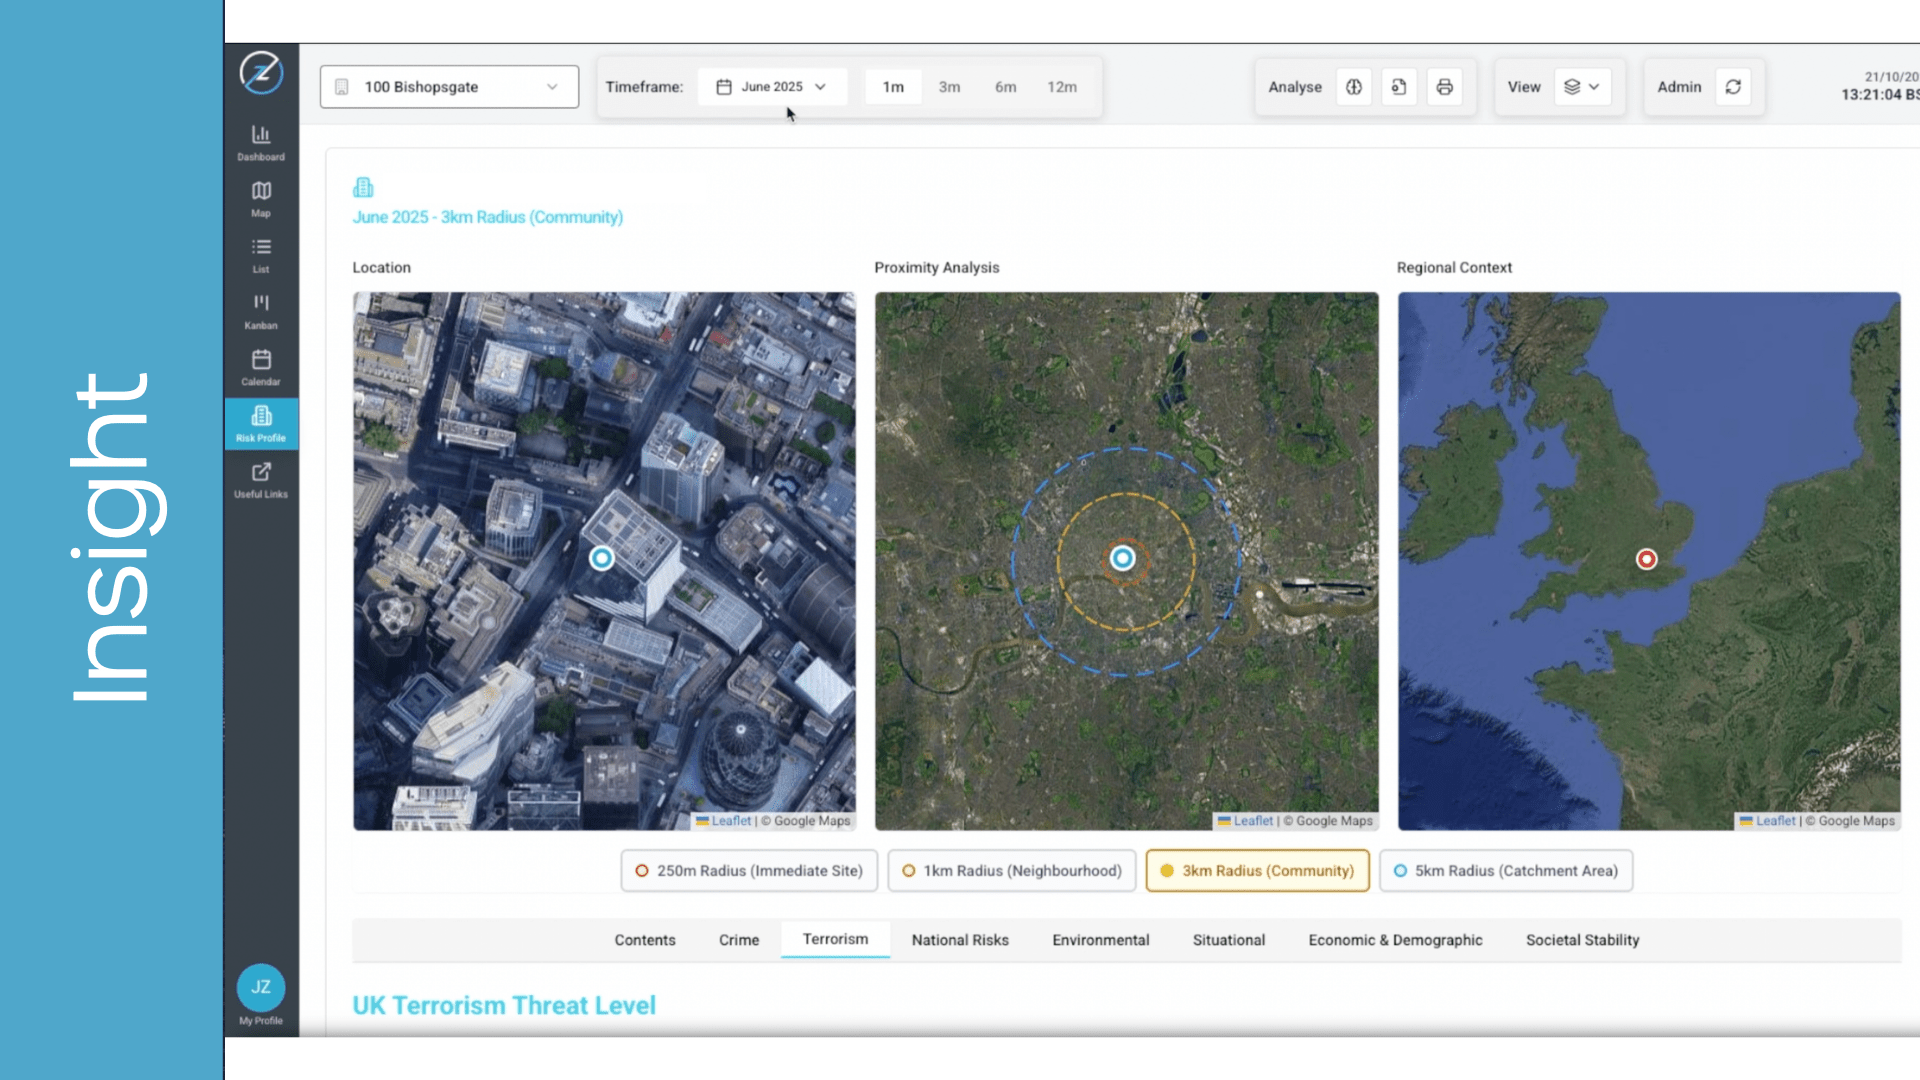
Zinc’s incident management and case management tools bring reports, escalation, and shift handover into one live system, so the first five minutes of any incident are captured clearly from the start.


 +44 (0)20 3989 4859
 info@zinc.systems

